Tokens and Embeddings, Explained Simply
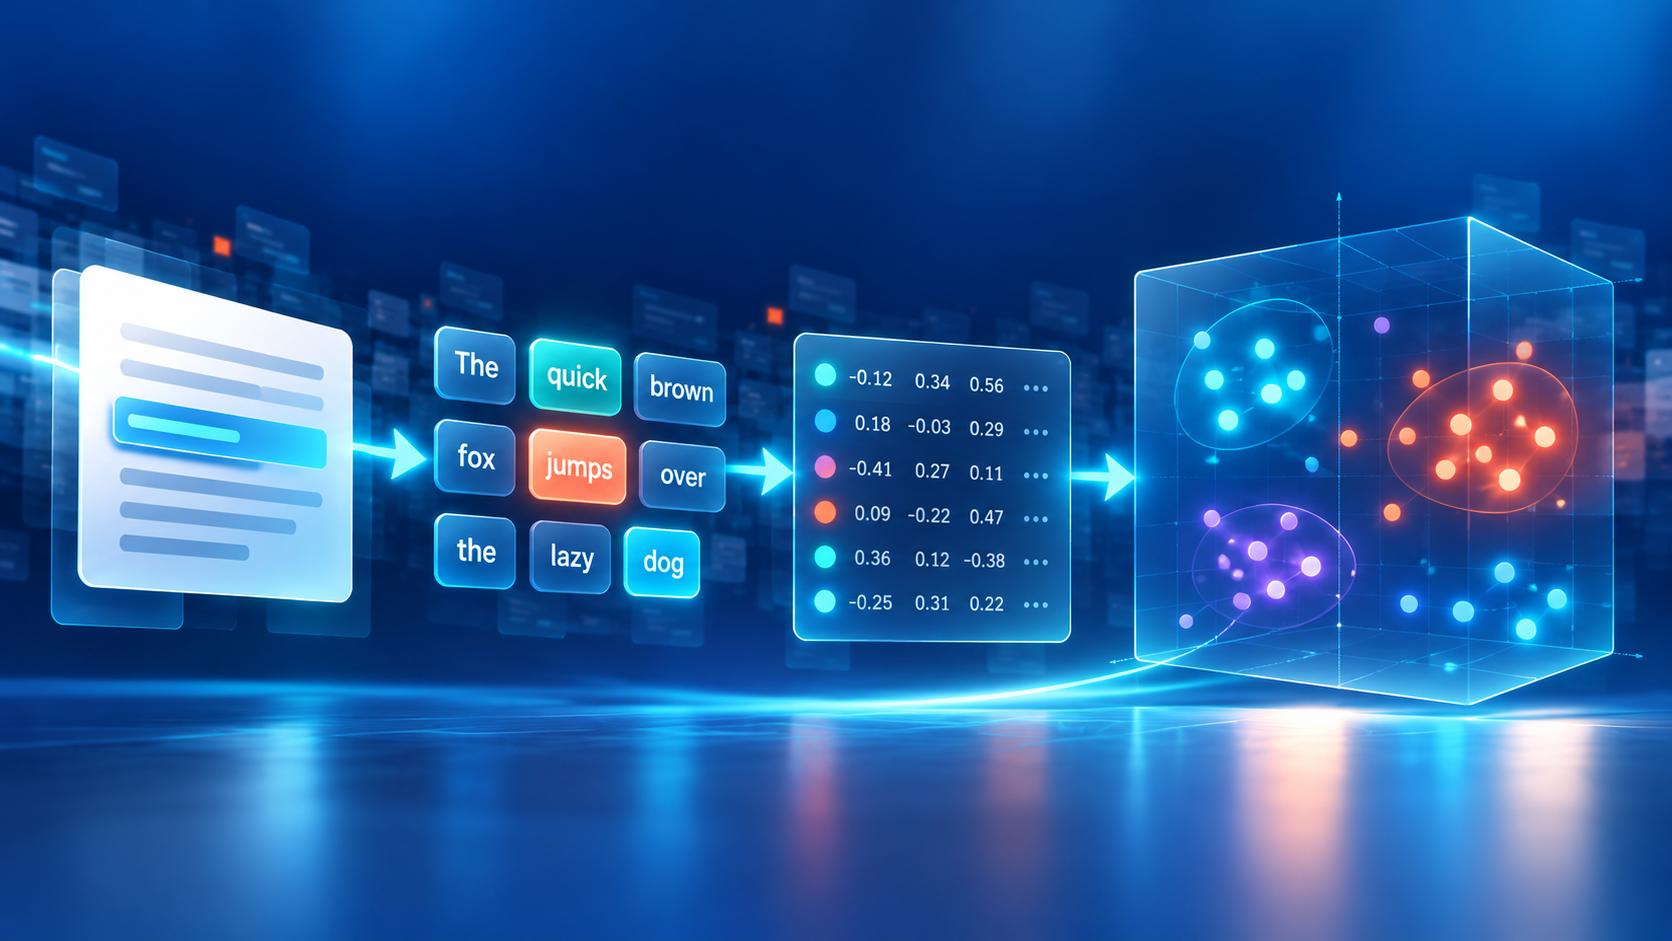
A model doesn't read words. It reads tokens: pieces of text that can be a character, part of a word, a whole word, or punctuation. Spaces matter too, so "red", "Red", and " red" can all become different tokens (OpenAI, n.d.-a). In English, a rule of thumb is about 4 characters, or three-quarters of a word, per token, so 75 words is roughly 100 tokens. Long or rare words get split into several pieces. For example, "unbelievable" may become "un", "believ", "able" (illustrative; splits vary by model).
Why you should care: tokens are what you pay for, and a model's context window is measured in tokens, not words. Other languages often need more tokens for the same meaning, which means higher cost.
What is an embedding?
An embedding is a list of numbers (a vector) that represents the meaning of a piece of text. Texts with similar meaning get vectors that sit close together, and closeness is usually measured with cosine similarity (OpenAI, n.d.-b). OpenAI's text-embedding-3-small returns 1,536 numbers per text; the large model returns 3,072.
So "refund" and "money back" have nearby vectors even though they share no words. That's how semantic search, clustering, recommendations, and RAG work.
How they connect
Text is split into tokens, tokens are converted to numbers, and those numbers capture meaning. Tokens are the input; embeddings are the meaning.