The KV Cache
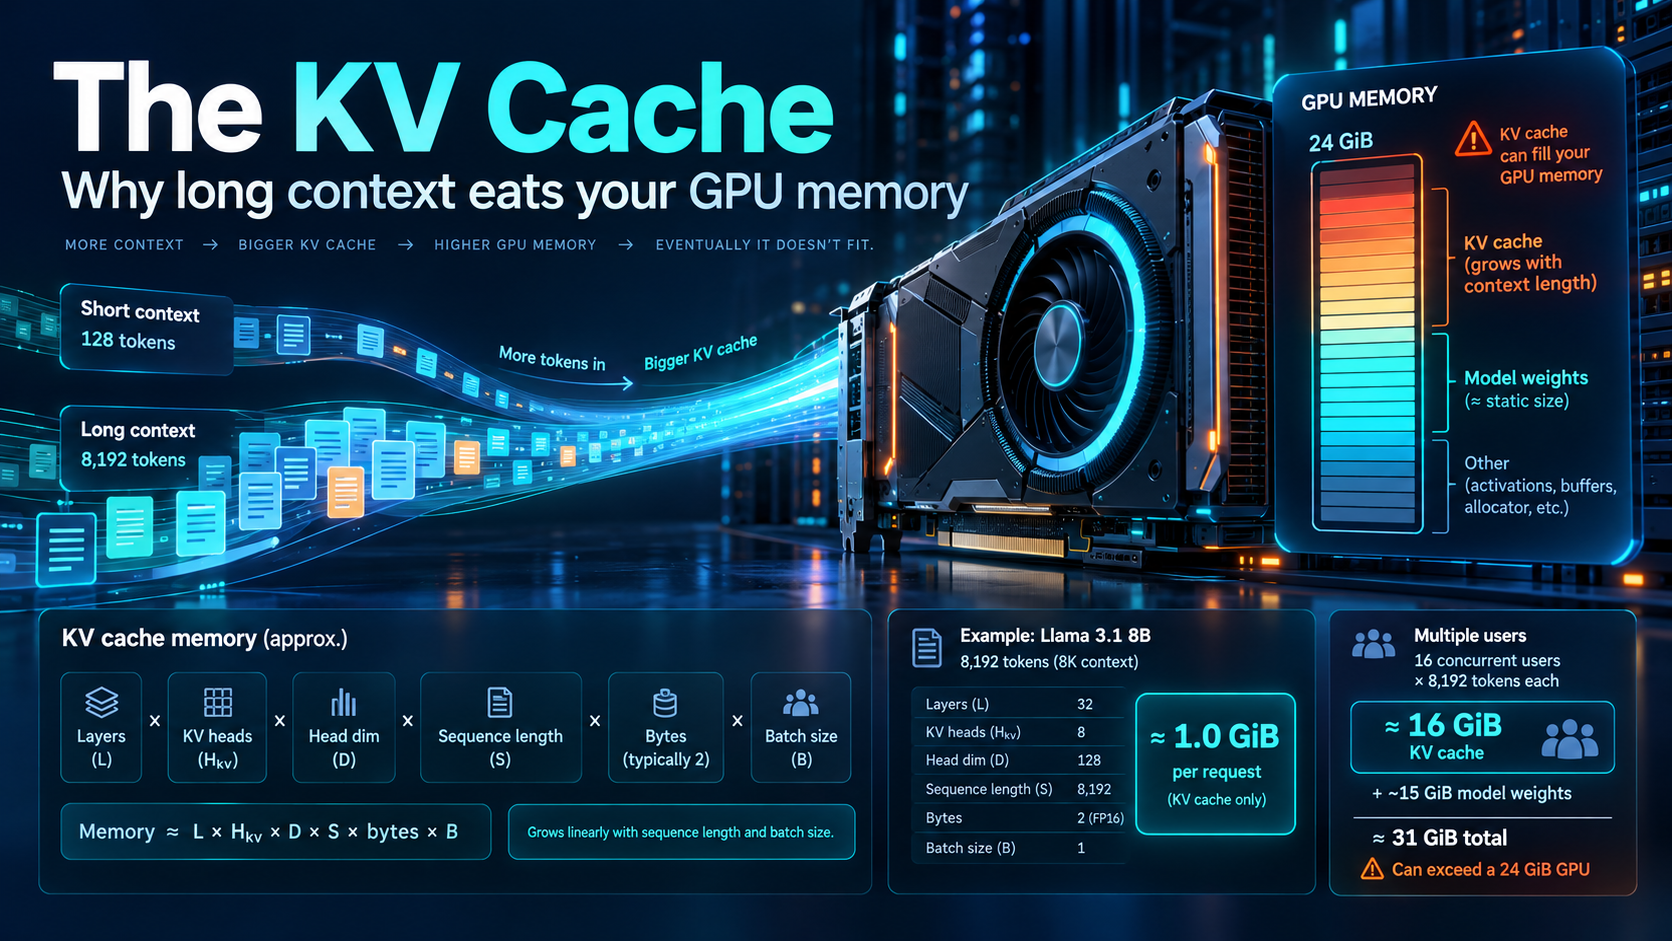
When an LLM generates text, each new token must "attend" to every previous token. That requires the Key (K) and Value (V) vectors of all earlier tokens at every layer. Recomputing them for each new token would be wasteful, so inference engines store them: the KV cache. It's why generation after the first token is fast, and why prompt caching exists.
The trade-off is memory. The cache grows linearly with context length and with the number of concurrent requests:
KV cache = 2 × layers × kv_heads × head_dim × seq_len × bytes_per_element × batch_size
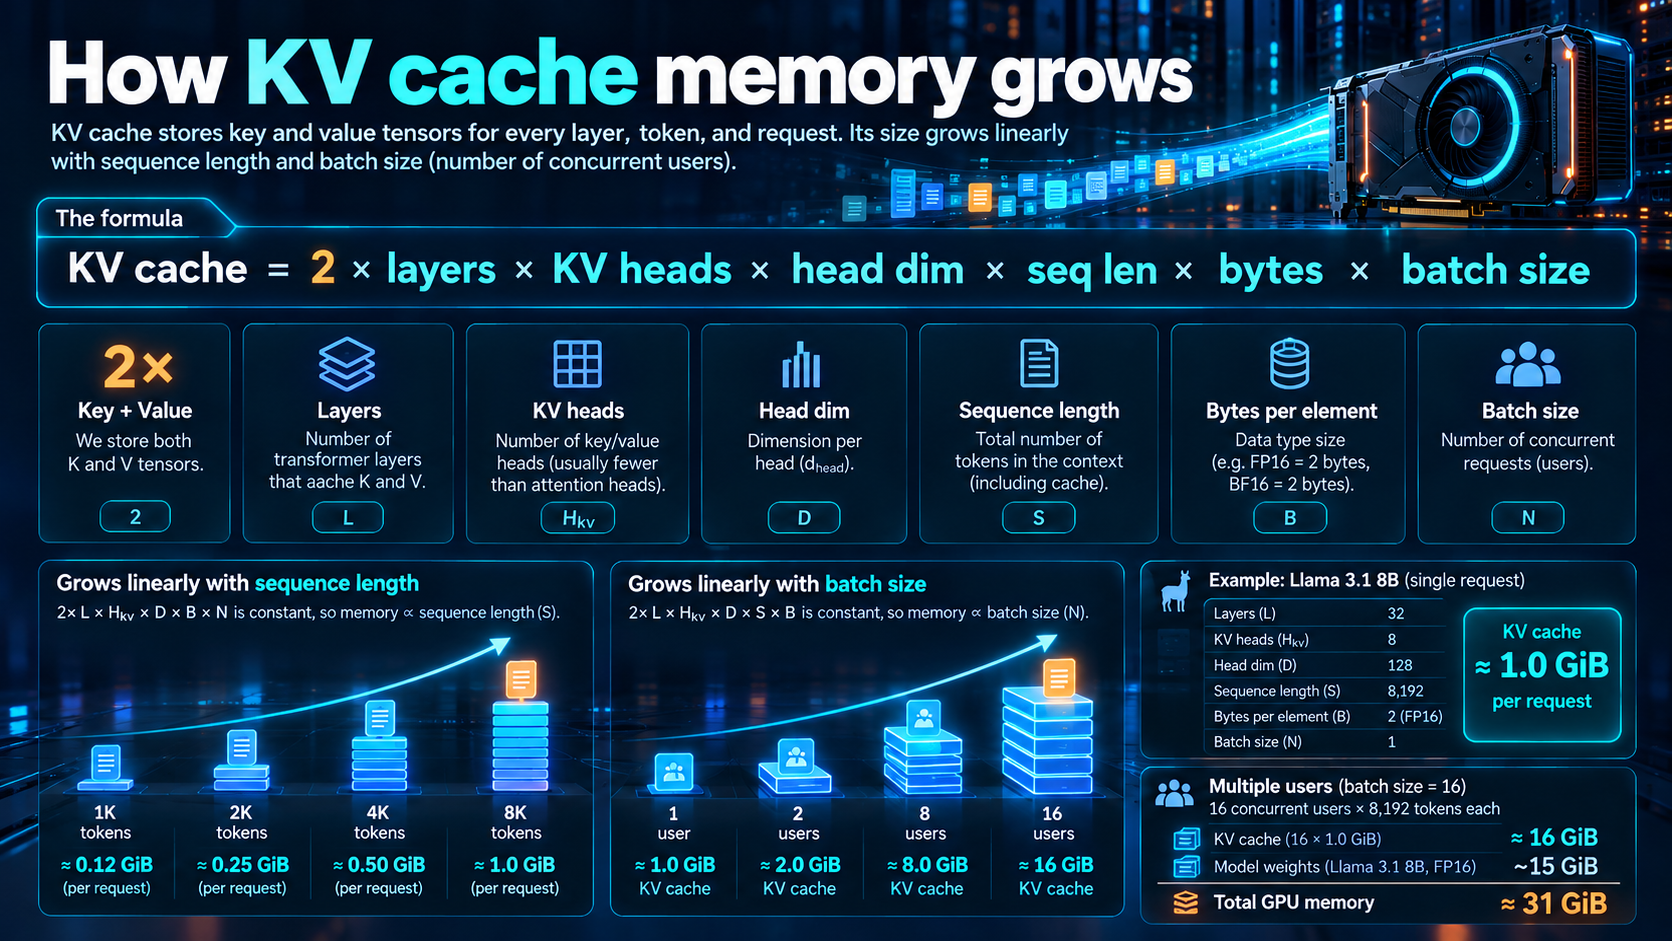
Worked example (Llama 3.1 8B, FP16): 32 layers, 8 KV heads, head dim 128, 8,192 tokens → 2 × 32 × 8 × 128 × 8192 × 2 bytes ≈ 1.0 GiB per request. Serve 16 users at once and the cache needs ~16 GiB, on top of ~15 GiB of weights. That already overflows a 24 GB consumer GPU.
How to solve it?
- Grouped-Query Attention (GQA): several query heads share one K/V pair. Llama 3.1 8B uses 8 KV heads instead of 32, a 4× smaller cache than standard multi-head attention.
- KV cache quantization: store the cache in FP8 (e.g. vLLM's
--kv-cache-dtype fp8), roughly halving it. For Mixtral-8x7B at 32K tokens, that goes from 4.29 to 2.15 GiB per request. - PagedAttention: manage the cache in small blocks to avoid fragmentation, allowing larger batches.
When you size hardware, pick a context window, or compare API prices, the bottleneck is often cache memory, not model size. Trim prompts and you save real money.
References
Ainslie, J., et al. (2023). GQA: Training generalized multi-query transformer models from multi-head checkpoints. arXiv. https://arxiv.org/abs/2305.13245
ApX Machine Learning. (2026). KV cache memory scaling. In Designing and Sizing Production LLM Infrastructure. https://apxml.com/courses/designing-and-sizing-production-llm-infrastructure/chapter-3-inference-dynamics-attention/kv-cache-memory-scaling
Kwon, W., et al. (2023). Efficient memory management for large language model serving with PagedAttention. SOSP '23. https://arxiv.org/abs/2309.06180