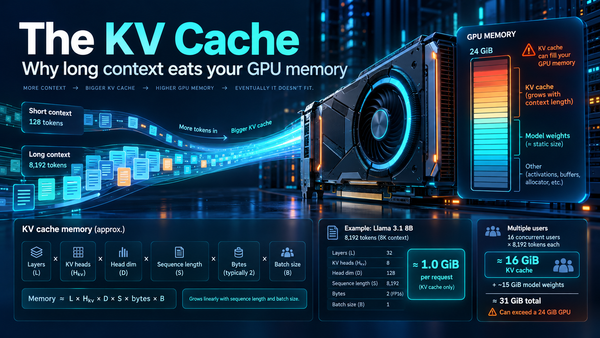
When an LLM generates text, each new token must "attend" to every previous token. That requires the Key (K) and Value (V) vectors of all earlier tokens at every layer. Recomputing them for each new token would be wasteful, so inference engines store them: the KV cache. It&