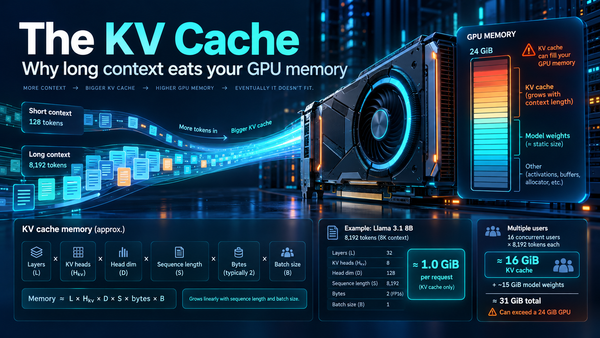
GPU Memory The KV Cache When an LLM generates text, each new token must "attend" to every previous token. That requires the Key (K) and Value (V) vectors of all earlier tokens at every layer. Recomputing them for each new token would be wasteful, so inference engines store them: the KV cache. It&
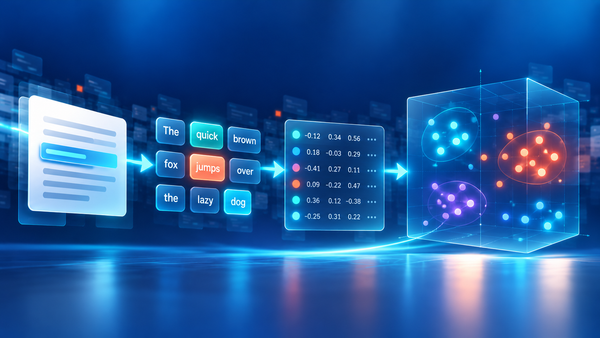
Token Tokens and Embeddings, Explained Simply A model doesn't read words. It reads tokens: pieces of text that can be a character, part of a word, a whole word, or punctuation. Spaces matter too, so "red", "Red", and " red" can all become different tokens (OpenAI, n.d.-a)