Your AI agent doesn't need the whole database
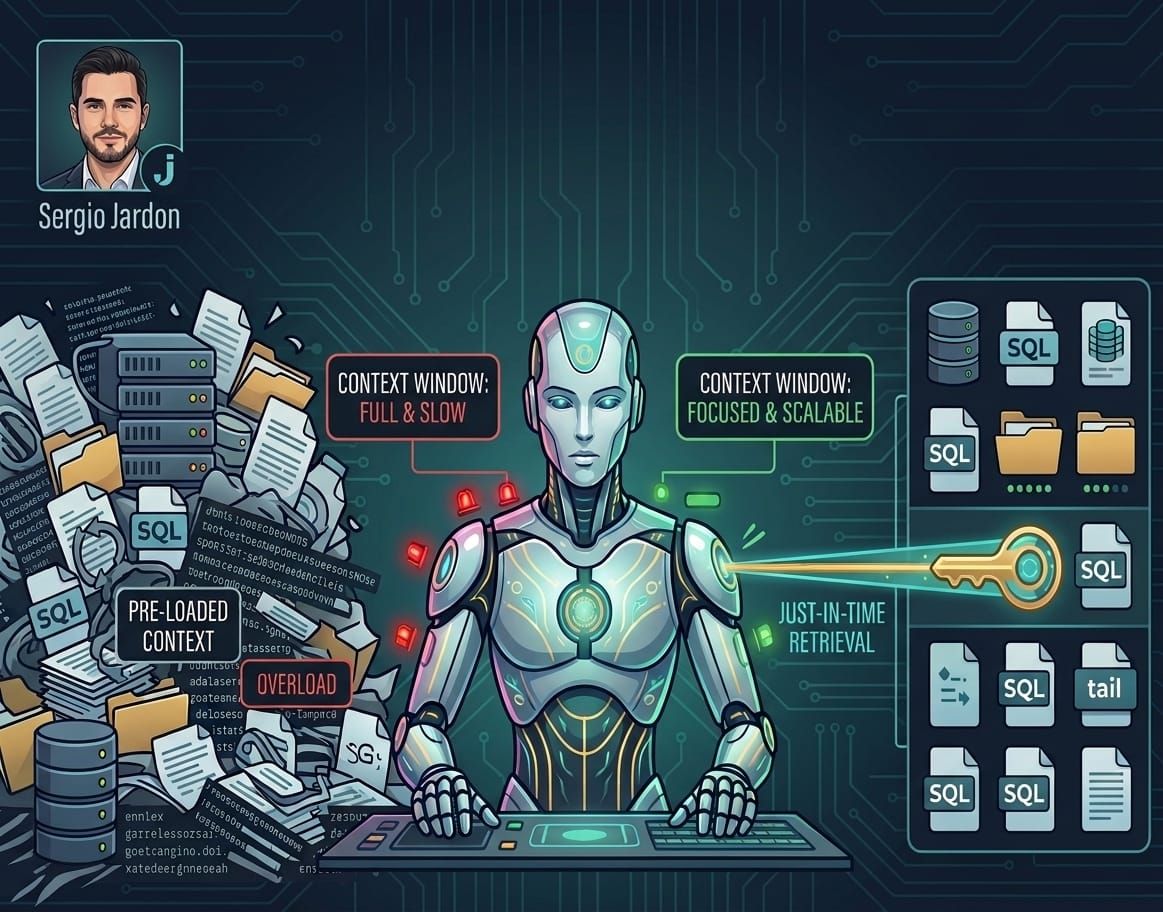
Here's a mistake I see when people build their first AI agent: they treat the context window like a bucket to fill. Got a customer database? Paste it in. A log file? Paste it in. In practice this backfires, the model gets buried in irrelevant rows, burns tokens it should spend reasoning, and starts missing the details that are important or relevant.
Anthropic's engineering team recently wrote up a fix for this called "just-in-time context retrieval" (Effective context engineering for AI agents). Instead of pre-loading everything the agent might need, give it lightweight references like file paths, search queries, a database connection, and a tool to resolve them at runtime.
A concrete before/after:
Bad practice:
Here is our full customer table (50,000 rows, pasted below).
Find customers who churned in Q3.
Better giving it a tool and a habit:
You have a query_db(sql) tool connected to the customers table. Start with a COUNT(*) query to scope the problem before pulling full rows. Only fetch the columns you need to answer the question.The second version is a little bit longer, but it changes the agent's approach: it scopes the problem first, then retrieves narrowly. It's the same principle behind how Claude Code handles large files: reaching for head and tail instead of loading the whole thing into context.
As agents take on longer, multi-step tasks, context isn't free. Every irrelevant row you hand over competes with the model's attention. Teaching your agent to fetch just-in-time instead of front-loading everything is one of the cheapest upgrades you can make to an agentic workflow, and it scales far better as your data grows.
References:
- Effective context engineering for AI agents. Anthropic's engineering blog, source for the "just-in-time context retrieval" pattern and the Claude Code
head/tailexample cited in the post.