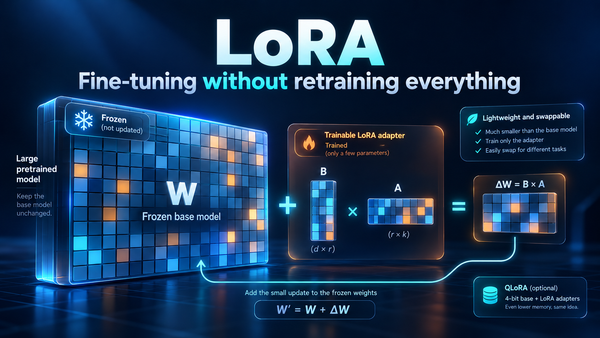
When prompting hits a ceiling, teams often assume fine-tuning means retraining billions of parameters on a GPU cluster. LoRA (Low-Rank Adaptation) is why that's no longer true.
The idea
Instead of updating a layer's full weight matrix W, LoRA freezes W and learns a