Agent Architecture Deep-Dive: Reflexion
Two weeks ago I covered ReAct, the foundational reason → act → observe loop that most agents are built on. ReAct reasons well within a single pass, but it has no mechanism for actually getting better when that pass fails. Reflexion fixes that gap.
How it works
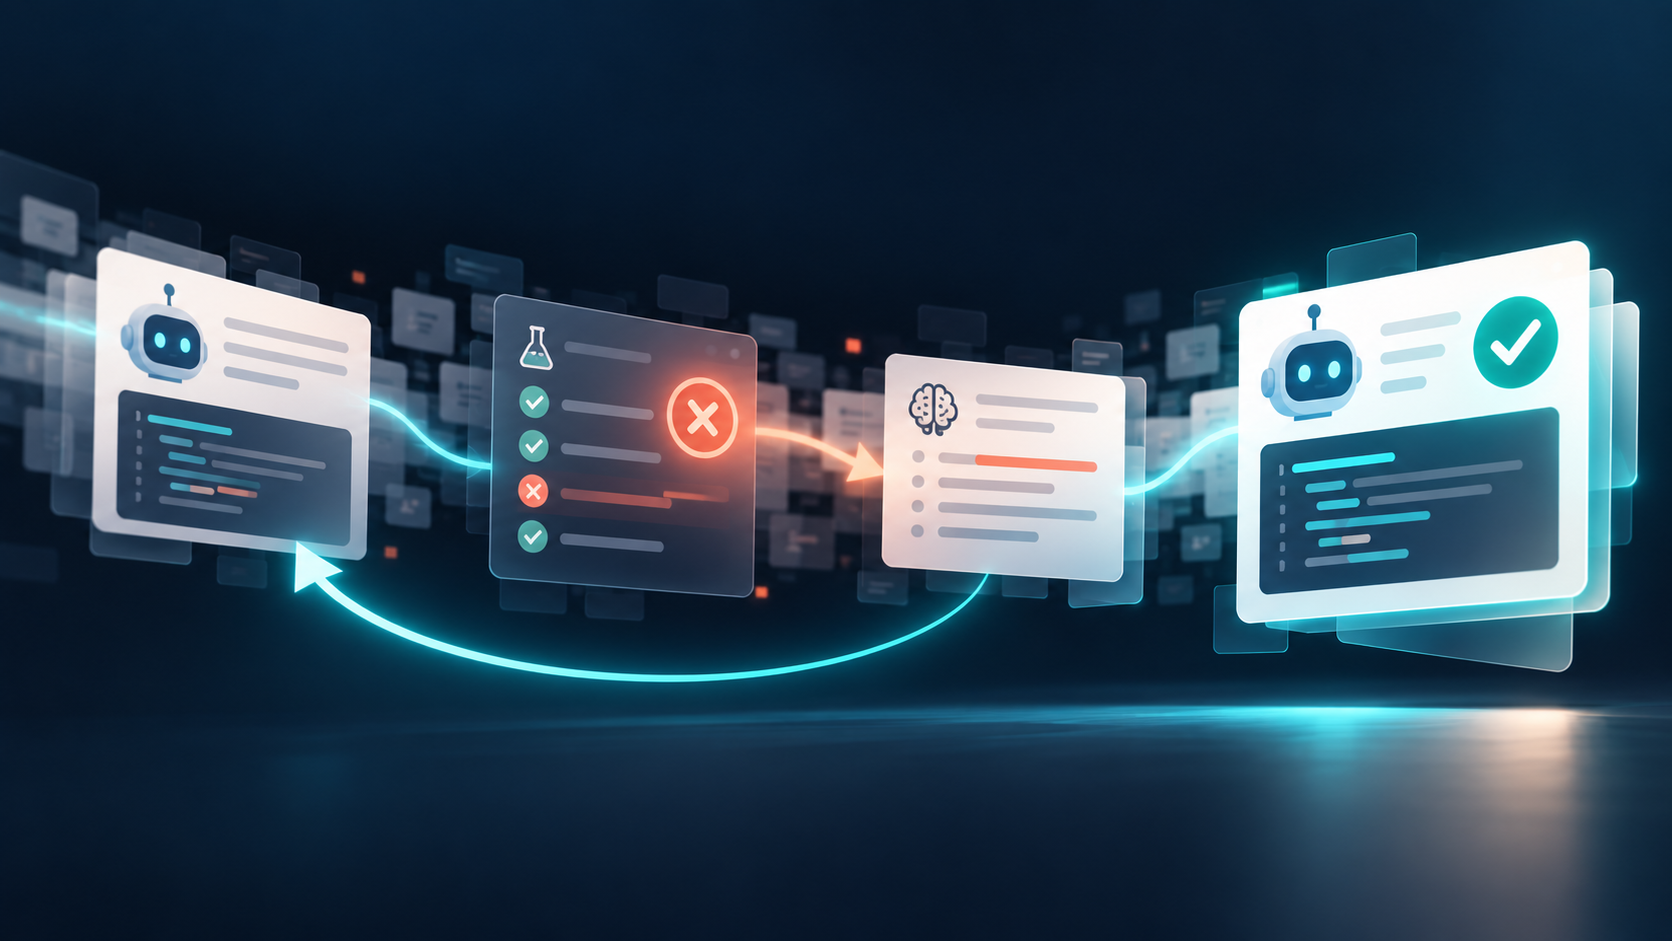
Reflexion wraps a task attempt in a three-part loop: execute, evaluate, reflect. The agent attempts the task (this can itself be a ReAct loop). An evaluator, ideally something automated, like unit tests for code, or a scoring rubric, checks whether the output actually succeeded. If it didn't, a reflection step generates a short natural-language critique of what went wrong ("the recursive case never terminates when the input list is empty") and writes it into episodic memory. The agent then retries the entire task again, but now with that critique in its context, so it doesn't repeat the same mistake blind. This repeats until the evaluator passes the output or a retry budget runs out.
The results can be significant: the original approach improved GPT-4's HumanEval pass rate from 80% to 91% purely by adding this self-critique loop, with no model fine-tuning involved.
Use Cases
Reflexion earns its cost when a task has a clear, checkable pass/fail signal and benefits from multiple attempts: iterative code debugging (retry against failing unit tests), agentic coding assistants, multi-step reasoning or math problems that can be automatically verified, and tool-use tasks where an API call's success or failure is unambiguous.
Weaknesses
Every retry is a full additional execution cycle plus evaluation and reflection overhead, so cost and latency multiply with each attempt, a poor fit for real-time or user-facing interactions where someone is waiting on a response. It also depends heavily on having a genuine, automated evaluator: tasks with subjective success criteria ("write a persuasive email") leave the evaluator unable to score reliably, which makes the resulting critiques vague and unhelpful. Most damaging, because the same model generates both the output and its own critique, Reflexion can reinforce its own blind spots: repeating the same misconception across retries rather than catching it and improvement tends to plateau fast, with most of the gain showing up in the first one or two retries and little left by the fourth or fifth.
Reflexion is the right tool when a task is verifiable and worth the extra compute to get right. For anything real-time, subjective, or where a single well-reasoned pass is good enough, plain ReAct is the better fit.
References
Shinn, N., Cassano, F., Berman, E., Gopinath, A., Narasimhan, K., & Yao, S. (2023). Reflexion: Language agents with verbal reinforcement learning. arXiv. https://arxiv.org/abs/2303.11366
Anthropic. (2024, December 19). Building effective agents. Anthropic Engineering Blog. https://www.anthropic.com/engineering/building-effective-agents
The AI Engineer. (2026). The 4 single-agent patterns: ReAct vs Plan-and-Execute vs ReWOO vs Reflexion. The AI Engineer (Substack). https://theaiengineer.substack.com/p/the-4-single-agent-patterns