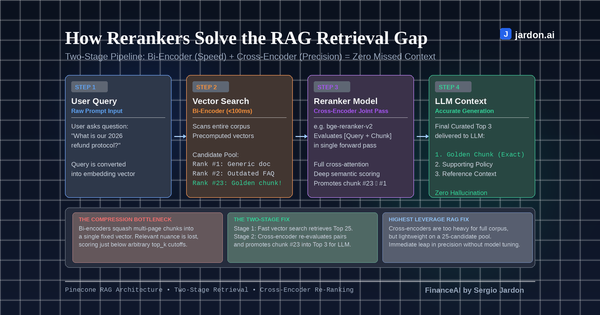
If you've built a retrieval-augmented generation (RAG) pipeline and found that answers are occasionally missing obvious context even though the right document is "in the knowledge base," the problem is usually the retrieval step, not the LLM.
Standard vector search relies on bi-encoders: models